Automatic speech recognition:
how it works and the history of ASR since 1952

ASR turns spoken words into written text. This guide covers what it is, how modern engines work, how accuracy is measured, and the history of speech recognition from Bell Labs' ten-digit Audrey in 1952 to 54+ languages today.

What is ASR?

Automatic speech recognition (ASR) is the technology that converts spoken language into written text. An ASR system takes an audio signal, analyzes the sounds in it and predicts the most likely sequence of words. It powers transcription software, voice assistants, live captions, dictation tools and voice search.

ASR stands for automatic speech recognition, and some vendors expand it as automated speech recognition; the two mean the same thing. For the two-minute version, read our ASR overview. This guide goes deeper, from the engine to the 70 years of research behind it.

The term gets tangled with three neighbors, and each answers a different question:

  • ASR (automatic speech recognition) converts speech audio into text and answers "what was said?"
  • Speech-to-text is the same technology under its product name; it also answers "what was said?"
  • Voice recognition (speaker recognition) identifies or verifies who is speaking and answers "who said it?"
  • NLP (natural language processing) interprets the meaning of text and answers "what does it mean?"

ASR and speech-to-text are interchangeable in practice: ASR is the engineering term, speech-to-text the product term. Voice recognition is the common mix-up. It recognizes a speaker, the way a phone unlocks only for its owner, while ASR transcribes anyone's words without caring who said them. NLP sits downstream: first the audio becomes text, then NLP summarizes it, answers a question about it or acts on it.

How does ASR work?

Modern ASR is one neural network that maps audio straight to text, but for most of its history it was a pipeline of five separate models.

The classic pipeline, which the history below builds piece by piece, works like this:

  1. Capture and preprocess. The audio is digitized, cleaned up and sliced into short frames, typically tens of milliseconds long.
  2. Feature extraction. Each frame becomes a compact numerical description of its energy at different frequencies.
  3. Acoustic model. This model maps those features to phonemes, the basic sound units of a language, and asks which sounds were probably made.
  4. Language model. This model knows which word sequences are likely, which is why an engine writes "recognize speech" rather than "wreck a nice beach": both fit the audio, only one fits the language.
  5. Decoder. The decoder searches the combined probabilities of the acoustic and language models and outputs the most likely sentence.

The end-to-end shift

Since the mid-2010s, end-to-end deep learning models, most of them now built on the Transformer architecture, learn the mapping from raw audio to text directly, trained on hundreds of thousands of hours of speech. There is no hand-built pronunciation dictionary and no separate acoustic model; the network learns all of it at once. That shift is the main reason transcription accuracy improved more in the 2010s than in the four decades before.

Because these models learn from audio at enormous scale, they handle accents, background noise and natural conversation far better than pipeline systems did, and they predict punctuation and capitalization in the same pass, so a modern transcript reads like a document.

How ASR accuracy is measured

The standard metric is word error rate (WER): the machine transcript is compared with a careful human transcript, and every substituted, deleted and inserted word counts as an error. A 5% WER means roughly one error every 20 words, or 95% accuracy. WER depends entirely on the test audio, which is why two vendors' accuracy claims are rarely comparable; our guide explains the formula and includes a calculator.

Speech recognition at a glance

Invented
Speech recognition was invented in 1952, when Bell Labs' Audrey system recognized the digits 0 to 9 spoken by a single voice.
First consumer software
Dragon Dictate, released in 1990 for about $9,000, was the first speech recognition product sold to the public, and it needed a pause after every word.
First 1,000-word vocabulary
Carnegie Mellon's Harpy understood 1,011 words in 1976, the target DARPA set for its five-year Speech Understanding Research program.
Human parity
In 2017 Microsoft measured a 5.1% word error rate on the Switchboard telephone benchmark, matching the professional transcribers who worked the same calls.
Open models
OpenAI's Whisper, released in September 2022, was trained on 680,000 hours of audio and transcribes nearly 100 languages with publicly released weights.
Today
Sonix, founded in 2017, transcribes 54+ languages with 99% accuracy and returns a one-hour recording in about 5 to 6 minutes.

The history of speech recognition starts at Bell Labs in 1952

The first speech recognizer was built at Bell Labs in 1952 and it understood exactly ten words: the digits zero through nine.

Audrey, the Automatic Digit Recognizer

K. H. Davis, R. Biddulph and S. Balashek built Audrey from analog circuits that filled a six-foot relay rack. A speaker said a digit into a telephone handset, the machine measured the vowel formants, and a lamp lit beside the digit it heard. Tuned to its designers' voices it scored 97 to 99 percent; with strangers it fell apart. Audrey never left the laboratory, because a human operator dialing numbers was cheaper, but it settled the question of whether a machine could hear at all.

IBM's Shoebox and the 1960s

In 1962 IBM demonstrated Shoebox at the Seattle World's Fair. It recognized 16 spoken words, the ten digits and six arithmetic commands, and drove an adding machine with them. Laboratories in the United States, Britain, Japan and the Soviet Union built recognizers for vowels and small word lists, and in 1968 Taras Vintsyuk described dynamic time warping, which let a machine compare speech spoken at different speeds. By 1969 the field had ambition but no theory, and John Pierce of Bell Labs compared it to schemes for turning water into gasoline.

DARPA's Speech Understanding Research program took vocabularies past 1,000 words

Between 1971 and 1976 DARPA funded the largest speech recognition effort to date, and Carnegie Mellon's Harpy reached its goal of 1,000 words.

The five-year goal

The Speech Understanding Research program asked for a system that could understand connected speech from several speakers over a 1,000-word vocabulary with under 10 percent error, and it paid Carnegie Mellon, BBN, SRI and others to compete. Harpy, finished at Carnegie Mellon in 1976, understood 1,011 words, roughly a three-year-old's vocabulary, and was the only system to meet the target. Its trick was a search that pruned unlikely word sequences early instead of weighing every possibility, an idea still at the heart of every decoder.

The statistical turn

The same years produced the idea that beat everything else for the next 40 years. At Carnegie Mellon, James Baker's 1975 thesis described the DRAGON system, which treated speech as a hidden Markov model and let probabilities, not hand-written rules, decide which words were said. At IBM, Fred Jelinek's group built the same approach into a research dictation system and added n-gram language models, so the recognizer could guess the next word from the last two. Bell Labs, meanwhile, moved from one voice to many and built recognizers that worked across speakers, which telephone applications required.

Hidden Markov models made speech recognition statistical during the 1980s

The 1980s replaced pattern matching with probability, and vocabularies grew from a few hundred words to 20,000 in a decade.

How a hidden Markov model hears

A hidden Markov model does not try to match a sound to a template. It asks which sequence of speech sounds most probably produced the audio it received, then which sequence of words most probably produced those sounds. Training on recorded speech sets the probabilities, so more data means a better recognizer, a property that would matter enormously once the internet arrived. Combined with n-gram language models, the HMM became the standard architecture in every research lab and stayed there until deep learning displaced it in 2012.

Tangora, Sphinx and the first products

IBM's Tangora recognized a 20,000-word vocabulary by the mid-1980s, though it needed a pause between words and training on each speaker. In 1988 Kai-Fu Lee's Sphinx system at Carnegie Mellon was the first to combine a large vocabulary, continuous speech and speaker independence in one recognizer. Dragon Systems, founded by James and Janet Baker in 1982, began selling recognition software for personal computers. Voice recognition reached consumers for the first time too: Worlds of Wonder's Julie doll answered a handful of spoken phrases in 1987, and telephone companies trialed voice dialing. The toys were crude, but they put the phrase "voice recognition" into ordinary homes.

The 1990s put speech recognition on personal computers

Faster processors turned dictation from a laboratory demonstration into shrink-wrapped software, and a shared benchmark made progress easy to measure.

Dragon Dictate to NaturallySpeaking

Dragon Dictate shipped in 1990 for about $9,000. It was the first speech recognition product a member of the public could buy, and it demanded a pause after every word. In 1997 Dragon NaturallySpeaking removed the pause: it recognized continuous speech at around 100 words a minute on a home PC, and IBM answered with ViaVoice the same year. For the first time a lawyer, a doctor or a writer could talk to a computer and get usable text, provided they trained it and corrected it.

Phone trees and the first benchmarks

In 1996 BellSouth launched VAL, a dial-in voice portal that answered spoken questions, and every automated phone system you have argued with since descends from it. Behind the scenes, DARPA and the National Institute of Standards and Technology ran yearly evaluations on shared recordings such as the Switchboard telephone corpus, and word error rate became the number every lab reported. From then on, the history of speech recognition is largely the history of that number falling.

The 2000s moved speech recognition into the cloud

Accuracy stalled near 80 percent for most of the decade, until Google moved recognition off the device and onto its servers.

The plateau

By 2001 the best systems transcribed dictated speech at roughly 80 percent accuracy, and the following years brought refinements rather than leaps. Desktop dictation stayed a niche, the phone-tree systems stayed frustrating, and research funding thinned. The hidden Markov model was near its ceiling, and the models that would replace it did not yet have the computing power or the data they needed.

Google Voice Search

Google's GOOG-411 directory service, launched in 2007, collected millions of spoken queries. In November 2008 Google Voice Search arrived as an iPhone app, and recognition changed shape: the phone only recorded, and the recognition ran in Google's data centers on models far larger than any device could hold, trained on 230 billion words of search queries. Recognition became a service rather than a program, the form it still takes.

Timeline

The history of speech recognition,
year by year

Every event below is dated. The sections around this table explain why each one mattered.

YearMilestoneWhy it mattered
1952Bell Labs builds AudreyThe first machine to recognize speech: the digits 0 to 9 from one speaker
1962IBM demonstrates Shoebox16 words, shown to the public at the Seattle World's Fair
1971DARPA starts the Speech Understanding Research programFive years of funding and a 1,000-word target
1976Carnegie Mellon's Harpy meets the target1,011 words, with a pruned search that decoders still use
1986IBM's Tangora hits 20,000 wordsHidden Markov and n-gram language models become standard
1988Sphinx at Carnegie MellonContinuous speech, speaker independence and a large vocabulary in one system
1990Dragon Dictate shipsThe first speech recognition product sold to consumers
1997Dragon NaturallySpeaking and IBM ViaVoiceContinuous dictation on a home PC at about 100 words a minute
2008Google Voice SearchRecognition moves to the cloud and learns from every query
2011Apple ships SiriA mainstream phone ships with a voice assistant
2012Deep neural networks replace Gaussian mixture modelsError rates fall by as much as a third in one step
2016Microsoft reports 5.9% on the Switchboard benchmarkThe first claim of human parity on a conversational benchmark
2017Microsoft 5.1%, IBM 5.5%, Google 4.9%; the Transformer is publishedThe parity race ends and the next architecture arrives
2020wav2vec 2.0 and the ConformerSelf-supervised learning cuts the need for labeled data
2022OpenAI releases Whisper680,000 training hours, nearly 100 languages, open weights

Deep learning cut error rates by more than half in the 2010s

Between 2011 and 2017 the word error rate on conversational telephone speech fell from the low teens to about 5 percent, and voice assistants moved into the home.

Siri and the assistants

Apple shipped Siri with the iPhone 4S in October 2011, Amazon followed with Alexa on the Echo in 2014, and Google with Google Home in 2016. The assistants mattered less for their recognition, which ran in the cloud much like Google Voice Search, than for the habit they formed: hundreds of millions of people started talking to machines every day, and every utterance became training data.

The neural network step

In 2012 researchers from Microsoft, Google, IBM and the University of Toronto, Geoffrey Hinton among them, published a joint paper showing that deep neural networks trained on the acoustic side of the problem cut error rates by up to a third compared with the Gaussian mixture models that HMM systems had used for 25 years. Baidu's Deep Speech went further in 2014 and trained a single recurrent network end to end, from audio to characters, with no pronunciation dictionary and no hand-built pipeline. Recognition became a deep learning problem, and the labs with the most GPUs and data pulled ahead.

The race to human parity

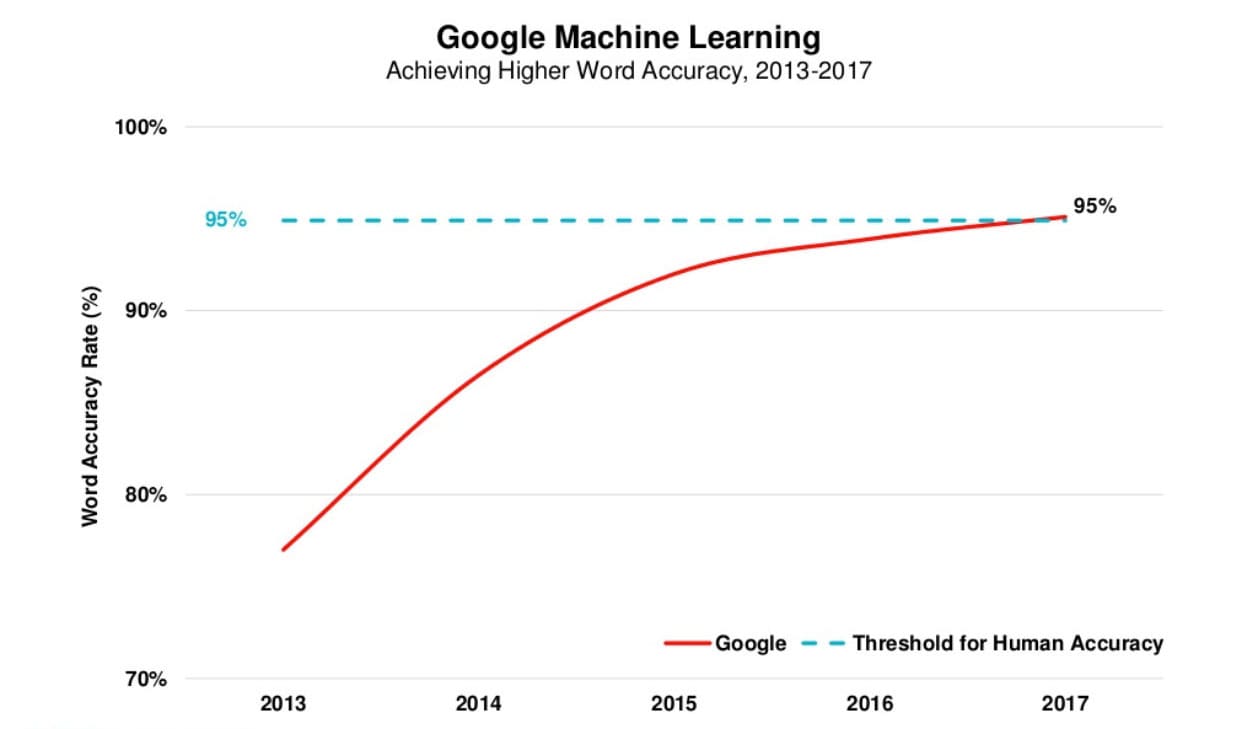
The Switchboard benchmark, a set of recorded telephone conversations, became the scoreboard. In October 2016 Microsoft reported a 5.9 percent word error rate, the same as the professional transcribers it hired to work the same calls, and called it human parity. IBM answered with 5.5 percent in March 2017, Google announced 4.9 percent on its own test sets that May, and in August 2017 Microsoft reached 5.1 percent against a more careful human baseline. The chart below, from Mary Meeker's 2017 Internet Trends report, shows Google's word accuracy crossing the 95 percent mark. The same year the Transformer architecture was published, and within three years it had taken over speech as well.

Chart of Google's word accuracy rate passing 95 percent, from Mary Meeker's 2017 Internet Trends report

Whisper and the Transformer made transcription a commodity

Self-supervised training and one open model turned accurate multilingual transcription from a Big Tech capability into something any product can offer.

Learning from unlabeled audio

The bottleneck of the 2010s was labeled data: every training hour needed a human transcript. In 2020 Facebook AI's wav2vec 2.0 learned speech representations from raw, untranscribed audio first and needed as little as ten minutes of labeled speech to fine-tune a usable recognizer. Google's Conformer, published the same year, combined convolution with Transformer attention and set new records on the standard benchmarks. Together they made the Transformer the default architecture for speech and cut the cost of adding a new language.

Whisper

In September 2022 OpenAI released Whisper, trained on 680,000 hours of audio collected from the web, covering nearly 100 languages, with the model weights published for anyone to run. It was not the most accurate system on every benchmark, but it was robust to accents, background noise and technical vocabulary in a way earlier academic models were not, and it was free. Within months it was inside thousands of products, and the question for transcription companies shifted from whether they could recognize speech to what they built around the transcript.

Automatic language identification has its own history

Knowing which language is being spoken is a separate problem from knowing which words, and it took its own 50 years to solve.

From phoneme statistics to i-vectors

The first language identification experiments in the 1970s told languages apart by the statistics of their sounds. In the 1990s that became the phonotactic approach: run a phoneme recognizer, then ask which language's phoneme patterns fit best, and NIST began formal Language Recognition Evaluations in 1996. In the 2010s the i-vector, a compact summary of a recording borrowed from speaker recognition, produced systems that could name a language from a few seconds of audio.

Built into the model

Modern multilingual recognizers fold the two problems together. Whisper and its successors predict the language as the first token of the transcript, so identification is a by-product of recognition rather than a separate step. That is what lets one product handle 54+ languages without a separate recognizer for each, and why the language you speak has stopped being a limit on what you can transcribe.

Where ASR stands today

Modern ASR is close to solved on clear, well-recorded audio, so engines now differ on hard audio and on what they do once the transcript exists.

Benchmark scores between serious engines have converged, so the question for a vendor is no longer "what is your accuracy?" but how it handles your audio and what it does with the transcript. Sonix is a working example of production ASR in 2026:

Accuracy, measured honestly

Sonix reaches 99% accuracy on clear, high-quality audio and returns a one-hour recording in about 5 to 6 minutes with automated transcription. Every accuracy figure, ours included, depends on the audio, so the only benchmark that matters is a test on your own recordings.

Languages

Sonix transcribes and translates in 54+ languages. Whisper-era models made broad language coverage standard rather than exceptional, and accuracy in each language tracks how much training audio exists for it.

Real time

Real-time transcription streams captions in under 2 seconds while people are still speaking, a direct payoff of the end-to-end architecture.

Who said what

Engines now separate speakers automatically, a task called speaker diarization; our speaker diarization guide explains how it works and where it still struggles.

Beyond the transcript

Summaries, chapters and translation turn raw text into something you can act on. ASR has become the first stage of an understanding pipeline rather than the end product, and your first 30 minutes on Sonix are free to see it on your own audio.

Where ASR is going: hard audio, privacy and understanding

The benchmark race is over, and the problems left are the unglamorous ones: hard audio, private deployment and turning words into understanding.

The hard cases

Overlapping speakers, far-field microphones, heavy accents, switching languages mid-sentence and specialized vocabulary still degrade every engine, ours included. End-to-end models also introduced a new failure mode: they occasionally hallucinate fluent text during silence or noise, an active research problem rather than a solved one.

On the device

Expect more recognition to run on phones, laptops and earbuds instead of in the cloud, for privacy and for speed. The same compression work that shrank Whisper-class models is bringing accurate recognition to hardware that never sends audio anywhere.

From transcript to understanding

Large language models now summarize meetings, answer questions about an interview and draft the follow-up from a lecture, and they do it well only because the transcript underneath is accurate. Voice keeps growing as an interface; the claim that it will replace every screen has been made since the 1990s, and we would settle for it reliably capturing what people actually said.

Common questions

ASR and speech recognition,
the questions answered

What does ASR stand for?

ASR stands for automatic speech recognition, the technology that converts spoken language into written text. You will also see it expanded as automated speech recognition; both mean the same thing. In transcription, ASR, speech recognition and speech-to-text are used interchangeably.

Is ASR the same as speech-to-text or voice recognition?

ASR and speech-to-text are the same thing: ASR is the technical term, and speech-to-text describes its output. Voice recognition is different. It identifies who is speaking from the characteristics of a voice, which is how a phone unlocks for its owner, while ASR transcribes what was said by anyone.

How is ASR different from NLP?

ASR converts speech audio into text; NLP (natural language processing) interprets what text means. They work in sequence: when you ask a voice assistant a question, ASR transcribes your words, then NLP works out the intent and the answer. In Sonix, ASR produces the transcript and NLP-based features summarize and analyze it.

How accurate is ASR?

On clear conversational recordings the best systems match professional transcribers: Microsoft measured a 5.1% word error rate on the Switchboard benchmark in 2017, and models have improved since. Sonix reaches 99% accuracy on good audio. Background noise, distant microphones, heavy accents and crosstalk still raise the error rate, so test on your own recordings.

When was speech recognition invented, and where?

In 1952. Bell Labs' Audrey system, built by K. H. Davis, R. Biddulph and S. Balashek, recognized the spoken digits 0 to 9 from a single speaker. IBM's Shoebox followed in 1962 with 16 words, and the first product you could buy, Dragon Dictate, arrived in 1990.

Who invented speech recognition?

No single person. Three Bell Labs engineers built the first recognizer, Audrey, in 1952. James Baker and Fred Jelinek made recognition statistical with hidden Markov models in the 1970s, Kai-Fu Lee's Sphinx made it continuous and speaker-independent in 1988, and Geoffrey Hinton's collaborators brought deep learning to it in 2012.

Which speech recognition software came first?

Dragon Dictate, released by Dragon Systems in 1990 for about $9,000, was the first speech recognition software sold to the public. It required a pause between words. Dragon NaturallySpeaking, released in 1997, was the first widely adopted continuous-speech dictation software for home computers.

Can ASR transcribe languages other than English?

Yes. Multilingual training data has made broad coverage standard, and modern systems handle dozens of languages. Sonix transcribes and translates in 54+ languages, including Spanish, French, German, Mandarin, Japanese and Arabic. Accuracy varies by language and tracks how much training audio exists for each one.

Get started

Try Sonix for free

Sonix transcribes, timestamps, and organizes your audio and video files so you can search, edit, and share your media.

Includes 30 minutes of free transcription

Keep reading

99% accuracy. Every word matters.

AI transcription and translation in 54+ languages.

30 minutes free
No credit card
Cancel anytime